
Server maintenance is defined as the regular, scheduled process of performing technical upkeep on servers to keep them secure, reliable, and available for business operations. For IT managers and business owners in Queensland, understanding what server is maintenance means in practice is the difference between predictable uptime and costly, unplanned outages. Scheduled maintenance is the most cost-effective way to reduce downtime risk and meet compliance requirements, particularly given that 42% of cyberattacks target small businesses. The industry term for this discipline is “preventative server maintenance,” and it covers everything from daily health checks to monthly security audits.
What does server maintenance actually involve?
Server maintenance is not a single task. It is a structured programme of daily, weekly, and monthly activities that prevent performance degradation before it becomes a crisis.
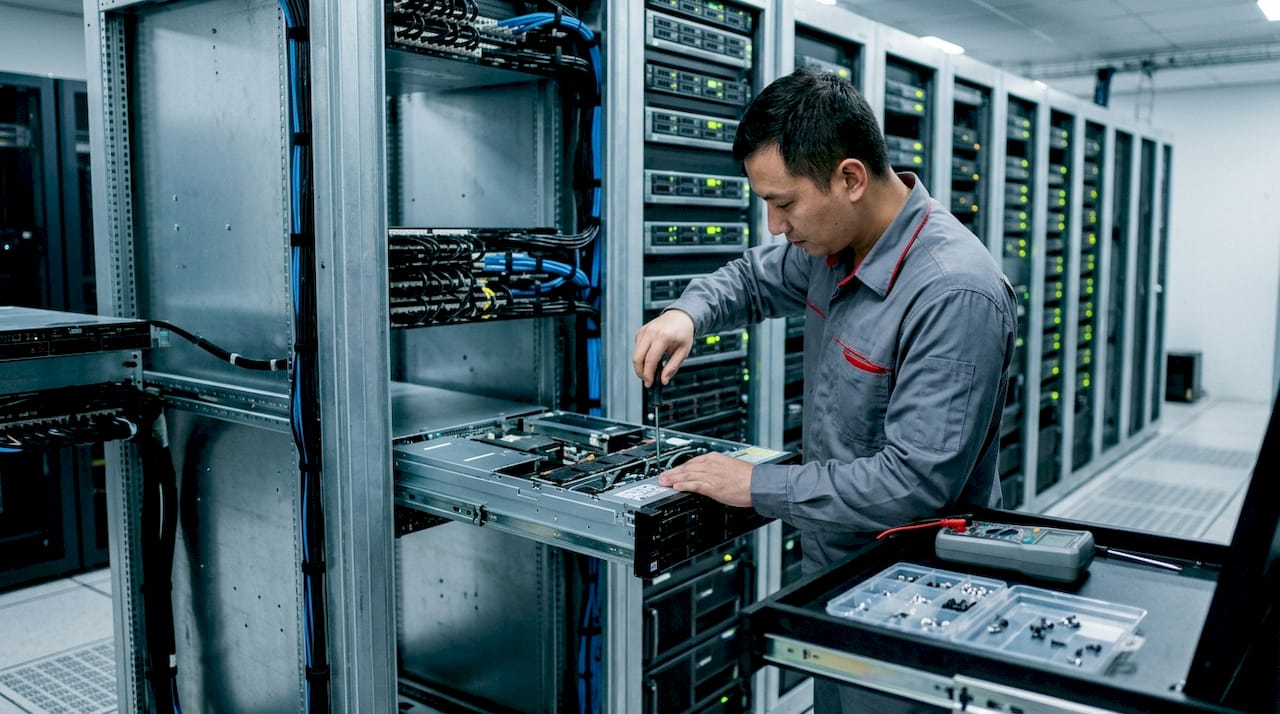
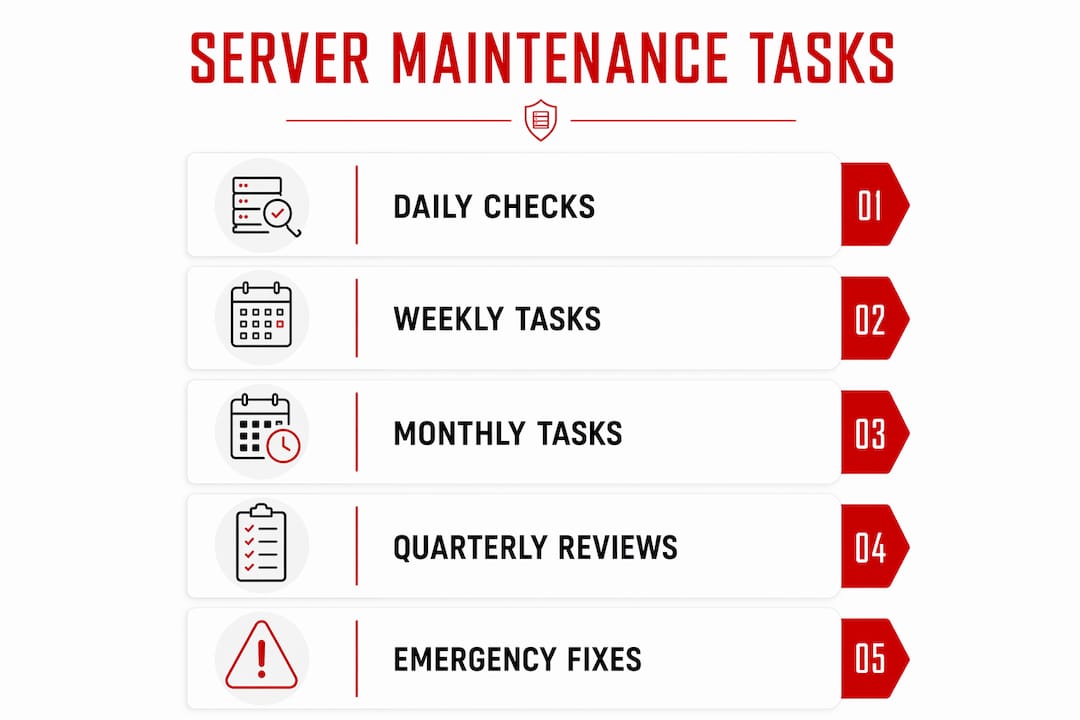
A well-designed maintenance routine follows a cadence-based schedule: daily checks take around 10 minutes, weekly tasks take 10–15 minutes, and monthly reviews take 30–45 minutes. That time investment is modest compared to the hours lost recovering from an avoidable outage.
Daily tasks (10 minutes)
- Service availability check. Confirm that all critical services, web servers, databases, and authentication systems are running and responding.
- Disk usage review. Flag any volume above 80% capacity. Log files are the most common culprit for silent disk growth.
- Error log scan. Look for repeated error codes or authentication failures that signal a developing problem.
- Backup job confirmation. Verify that the previous night’s backup completed without errors.
Weekly tasks (10–15 minutes)
- Patch management. Apply operating system and application security patches. Unpatched systems are the most common entry point for attackers.
- Backup verification. Check that backup files are intact and accessible. A logged success does not mean the data is actually recoverable.
- Resource trend review. Compare CPU, memory, and network usage against the previous week to spot upward trends early.
Monthly tasks (30–45 minutes)
- Full performance review. Analyse capacity trends and identify any services consuming disproportionate resources.
- Security audit. Review user accounts, firewall rules, and open ports. Remove any accounts or services that are no longer needed.
- Certificate expiry check. Confirm that SSL/TLS certificates are valid for at least another 60 days.
- Hardware health check. Review SMART data for drives and check physical indicators like fan speeds and temperatures.
Pro Tip: Set calendar reminders for weekly and monthly tasks the same way you schedule team meetings. Maintenance that is not calendared does not happen.
Routine prevents cumulative degradation. Each skipped check adds a small layer of risk. Over weeks and months, those layers compound into the kind of failure that takes hours or days to resolve.
How do maintenance windows affect server downtime?
Planned downtime is a deliberate trade-off. A short, scheduled outage is far less damaging than an unplanned one that hits during business hours with no warning.
Maintenance windows for enterprise systems typically run between 1 and 5 hours. That range reflects the complexity of the task, not carelessness. Kernel reboots, major patch cycles, and hardware replacements all require the system to be offline. Trying to avoid this reality leads to servers running outdated kernels for months, which is a security risk, not a win.
The goal is to make planned downtime predictable and minimally disruptive. Several strategies achieve this:
- Schedule during low-usage periods. For most Queensland businesses, this means late Sunday nights or early Saturday mornings. Analyse your traffic logs to confirm when usage genuinely drops.
- Communicate in advance. Notify internal stakeholders and clients at least 48 hours before a maintenance window. A brief, plain-language notice prevents confusion and builds trust.
- Set a realistic window. Overestimate the time needed. Finishing early is a win. Running over without warning is a problem.
- Test in staging first. Apply patches to a non-production environment before the maintenance window. This catches conflicts before they affect live systems.
- Document every change. Log what was done, when, and by whom. This record is invaluable if something behaves unexpectedly after the window closes.
The communication piece is underrated. Most stakeholder frustration during maintenance comes from surprise, not the downtime itself. A clear, timely notice turns a potential complaint into a non-event.
What causes server degradation outside of maintenance?
Most server failures do not arrive as sudden catastrophes. They build slowly from overlooked tasks and unresolved minor issues.
Infrastructure problems like hypervisor instability and traffic spikes are well-documented triggers. A June 2026 GitHub availability incident recorded 17% request failure rates and latency spikes reaching 800ms during an authentication failure event. That kind of degradation happens fast and affects every user simultaneously. Regular maintenance catches the conditions that make systems vulnerable to these spikes before they escalate.
| Degradation cause | How maintenance prevents it |
|---|---|
| Log file growth | Weekly log rotation and size monitoring |
| Expired SSL certificates | Monthly certificate expiry audits |
| Unpatched vulnerabilities | Weekly patch management cycles |
| Disk space exhaustion | Daily disk usage checks with alerts |
| Unused open ports | Monthly firewall rule reviews |
Slow degradation from overlooked tasks is the most common root cause of server incidents. Unchecked log file growth fills disks. Expired certificates break encrypted connections without warning. Neither failure is dramatic until it is.
Pro Tip: Set automated alerts for disk usage above 80% and certificate expiry within 30 days. These two alerts alone prevent a significant proportion of avoidable outages.
Preventative maintenance catches slow resource leaks and expired certificates before they trigger outages. The mindset shift is from “fix it when it breaks” to “find it before it breaks.”
Best practices for server upkeep: what actually works
The best server maintenance programmes share one characteristic: they are boring. Boring means predictable. Predictable means reliable.
The following practices form the core of any effective server maintenance checklist:
- Test your backups, not just your backup jobs. Automated backups often miss configuration files or fail silently. Run a full restoration test at least once per quarter to confirm you can actually recover. A backup you have never tested is not a backup.
- Audit accounts and permissions monthly. Remove accounts belonging to former staff immediately. Review service accounts and confirm each one still has a legitimate purpose.
- Review firewall rules quarterly. Rules accumulate over time. Old rules for decommissioned services create unnecessary attack surface. Consistent security hygiene through routine auditing outperforms complex, one-off hardening projects.
- Prune unused services. Every service running on a server is a potential vulnerability. If a service is not needed, disable it.
- Establish a change control process. Log every change made to a server, including who made it and why. This log is your first resource when diagnosing unexpected behaviour.
- Schedule reboots inside planned windows. Rebooting after kernel updates inside weekly or biweekly maintenance windows avoids surprise downtime. Never reboot a production server outside a planned window unless there is an active incident.
- Automate where repetition is guaranteed. Log rotation, disk usage alerts, and patch downloads are good candidates for automation. Tasks requiring human judgement, like reviewing security audit findings, should stay manual.
Pro Tip: Create a simple maintenance log in a shared document or ticketing system. Even a one-line entry per task creates accountability and a paper trail that proves compliance during audits.
The server upgrade process fits inside this framework. Major upgrades, whether operating system versions or hardware replacements, should follow the same change control discipline as routine patches, with staging tests, communication plans, and documented rollback procedures.
Key takeaways
Scheduled, cadence-based server maintenance is the single most effective way to prevent unplanned downtime and reduce security risk for Queensland businesses.
| Point | Details |
|---|---|
| Maintenance is a cadence, not an event | Daily, weekly, and monthly tasks each serve a distinct purpose in preventing degradation. |
| Planned downtime beats unplanned outages | Maintenance windows of 1–5 hours are far less costly than emergency recovery from an avoidable failure. |
| Slow degradation is the real threat | Log growth, expired certificates, and unpatched systems cause most incidents, not sudden hardware failures. |
| Backup testing is non-negotiable | Automated backup jobs must be verified through actual restoration tests, not just log entries. |
| Security hygiene beats one-off projects | Routine account audits and firewall reviews prevent more incidents than complex hardening exercises. |
Why I think most businesses get server maintenance backwards
Most businesses treat server maintenance as something to do after a problem appears. I have seen this pattern repeatedly: a server runs fine for months, maintenance gets deprioritised, and then a disk fills up or a certificate expires and suddenly there is a crisis at 9am on a Monday.
The uncomfortable truth is that good server maintenance should feel anticlimactic. If your maintenance programme is working, nothing interesting happens. No alerts, no outages, no emergency calls. The goal is a rhythmic system mapped to daily, weekly, and monthly intervals that catches problems when they are still small.
What I have found actually works is treating maintenance tasks the same way you treat financial reporting: fixed cadence, documented outcomes, and someone accountable for each item. The businesses that do this well are not the ones with the most sophisticated monitoring tools. They are the ones with the most consistent habits.
The server upgrade process is where this discipline pays off most visibly. Businesses with mature maintenance programmes handle major upgrades without drama because they already have staging environments, change logs, and communication templates in place. Businesses without that foundation treat every upgrade as a gamble.
Proactive server care is not glamorous. It is the IT equivalent of changing your car’s oil on schedule rather than waiting for the engine to seize. The cost difference between the two approaches is not subtle.
— Ru
Techbug’s managed IT support for Queensland businesses
Running a consistent server maintenance programme takes time and discipline that many Queensland businesses simply do not have in-house.
Techbug provides managed IT support for businesses across Queensland, covering scheduled server maintenance, proactive monitoring, ransomware-safe backups, and security hygiene as part of an ongoing managed service. With over 30 years of combined experience, the Techbug team handles the routine work so your staff can focus on running the business. Whether you need a one-off server health check or a fully managed maintenance programme, Techbug’s vendor-agnostic approach means you get the right solution for your environment, not a locked-in package.
FAQ
What is server maintenance?
Server maintenance is the regular, scheduled process of performing technical upkeep on servers, including patching, backups, security audits, and hardware health checks, to keep them secure and available.
How long does a server maintenance window take?
Maintenance windows for enterprise systems typically run between 1 and 5 hours, depending on the complexity of the tasks being performed, such as kernel reboots or major patch cycles.
How often should servers be maintained?
Servers require daily checks (around 10 minutes), weekly patching and backup verification (10–15 minutes), and monthly performance and security reviews (30–45 minutes).
Why do backups need to be tested?
Automated backup jobs frequently miss configuration files or fail without generating an error. Restoration tests, run at least quarterly, confirm that data is actually recoverable when needed.
Does regular maintenance reduce cyberattack risk?
Regular maintenance significantly reduces risk. With 42% of cyberattacks targeting small businesses, consistent patching, account audits, and firewall reviews are among the most effective defences available.